Rehearsing the questions#
Founders rehearse the pitch. Far fewer rehearse the six questions that decide whether a partner leans in or reaches for the door: why now, why you, does 10% return the fund, what stops a fast-follower, who signs the first cheque, does revenue survive a month off. Pitch Dojo is a two-minute drill for exactly those six, built as a single self-contained HTML file with no backend.
Both sides of the table#
Pitch Dojo has two modes: one where a partner questions you, and one where you question the partner.
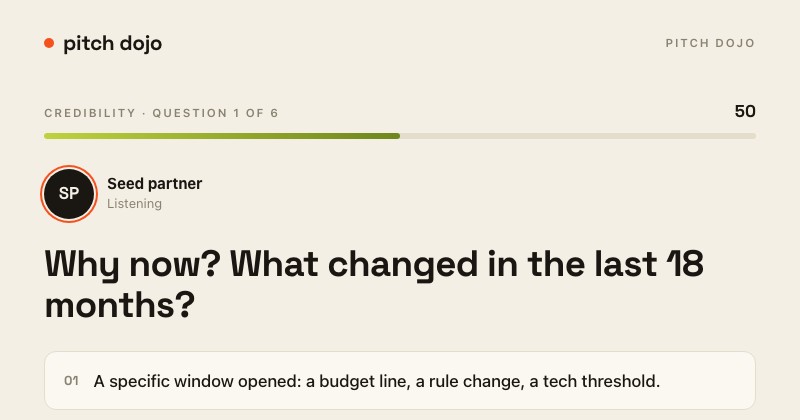
Get grilled. A seed partner fires the six questions one at a time. Every answer is graded sharp, okay or dodge, and a credibility meter moves live as you choose: +15 for the sharp answer, +5 for the generic-but-true one, -15 for the dodge that sounds fine and says nothing. The feedback explains why the sharp answer works, because the generic version of most of these answers sounds fine in the room and only falls apart afterwards.
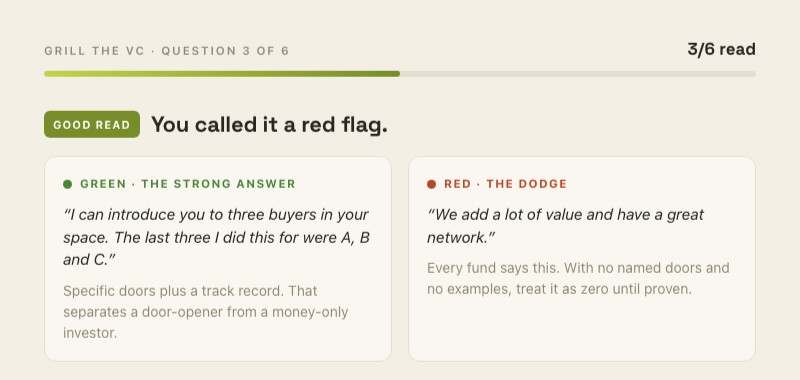
Grill the VC. The seats flip. You ask the six questions founders rarely think to ask back, on reserves, on real value-add, on process and timeline, on what a pass would look like, and you have to call whether the partner's answer is a green flag or a rehearsed dodge before the reveal shows you both side by side.
Reading a partner's answers#
A founder who can only answer well is still exposed on the other side of the table, because a fund's own answers are pitches too. "We add a lot of value and have a great network" is exactly as rehearsed as "we're passionate about the space," and it costs a founder real time and real terms if it goes unchallenged. Pitch prep rarely trains this half.
Every question in both modes traces back to a fixed rubric: named, dated specifics beat true-but-generic claims, and true-but-generic claims beat warmth with nothing behind it. The scoring logic and the content are plain arrays and pure functions you can inspect, checked by a small self-test suite (add ?test to the URL). It's deployed as a static app on Vercel.